Nested Recurrent Memory: Training Kernels
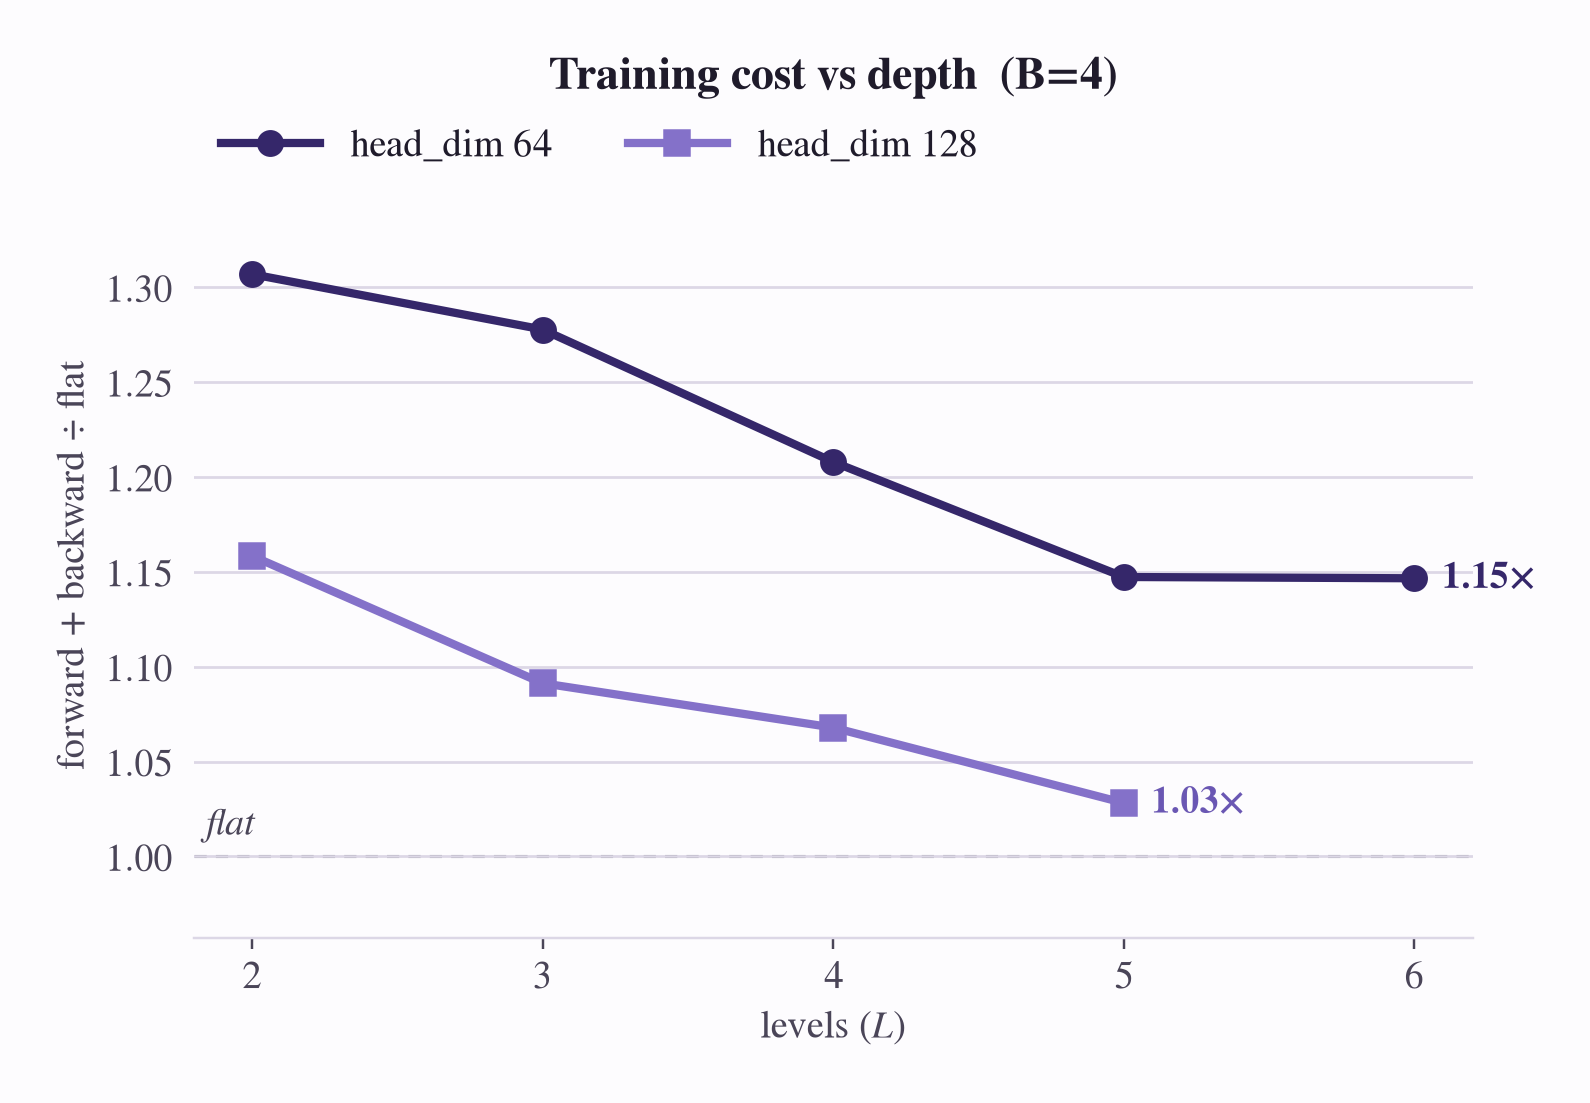
How the upper levels of a nested GDN-2 are implemented, and how it benchmarks against a flat GDN-2 with the same recurrent state: a slower forward, a backward that gets cheaper with depth, and much lower peak memory.